6.2 Using the Normal Distribution
🎲Intro to Statistics Unit 6 Review
6.2 Using the Normal Distribution
🎲 Intro to Statistics
Normal Distribution Calculations and Interpretation
The normal distribution gives you a way to calculate the probability of specific outcomes, like the chance a randomly selected test score falls above or below a certain value. To do this, you convert raw values into z-scores, then use tables or technology to find the corresponding probabilities.

Top images from around the web for Probability calculations in normal distributions
The Standard Normal Distribution | Introduction to Statistics View original
Is this image relevant?
The Normal Curve | Boundless Statistics View original
Is this image relevant?
Chapter 7: Normal distribution - Statistics View original
Is this image relevant?
The Standard Normal Distribution | Introduction to Statistics View original
Is this image relevant?
The Normal Curve | Boundless Statistics View original
Is this image relevant?
Probability Calculations in Normal Distributions
The total area under any normal curve equals 1 (or 100%), representing all possible outcomes. To find the probability associated with a specific value, you standardize it using the z-score formula:
- = the value you're interested in (e.g., a specific test score)
- = the mean of the distribution
- = the standard deviation of the distribution
The z-score tells you how many standard deviations is from the mean. A z-score of 1.5 means the value sits 1.5 standard deviations above the mean; a z-score of -2 means it's 2 standard deviations below.
Once you have the z-score, here's how to find probabilities:
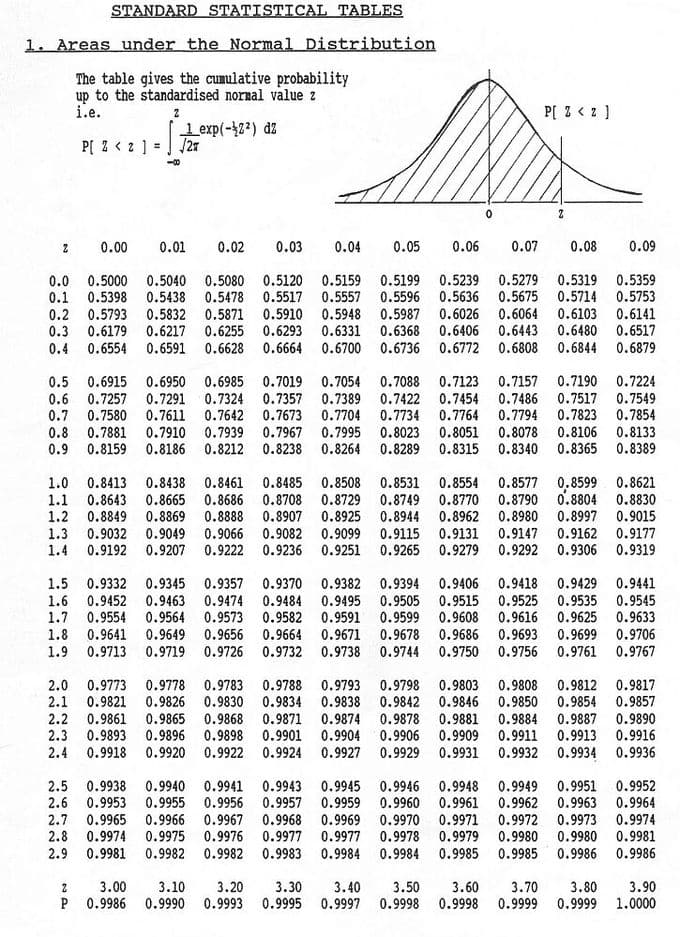
- Look up the z-score in a standard normal distribution table (or use technology). The table gives you the area to the left of that z-score.
- That area is the probability that a randomly selected value is less than or equal to .
- To find the area to the right, subtract the left-side area from 1. For example, if the area to the left is 0.8413, the area to the right is .
- Express the result as a decimal (0.1587) or a percentage (15.87%).
This left-side lookup is called the cumulative distribution function (CDF): it gives the probability that a random variable is less than or equal to a given value.

Interpretation of Shaded Areas
When you see a shaded region on a normal curve, that shaded area is the probability of a value falling in that region. There are three common setups:
- Area to the left of a z-score: the probability of a value being less than or equal to the corresponding -value. For example, the probability of scoring below 75 on an exam.
- Area to the right of a z-score: the probability of a value being greater than the corresponding -value. For example, the probability of scoring above 90.
- Area between two z-scores: the probability of a value falling within a specific range. You calculate this by finding the left-side area for each z-score and subtracting the smaller from the larger.
The empirical rule (68-95-99.7 rule) provides quick estimates without any table lookups:
- About 68% of data falls within 1 standard deviation of the mean
- About 95% falls within 2 standard deviations
- About 99.7% falls within 3 standard deviations
This is useful for ballpark checks, but for precise probabilities you'll still need the z-table or technology.

Using Technology for Normal Distribution Probabilities
Statistical software and calculators speed up these calculations and reduce errors. Common tools include graphing calculators (like the TI-84), spreadsheet software (like Excel or Google Sheets), and online z-score calculators.
General steps for using technology:
- Identify the parameters you need: the mean (), standard deviation (), and the value or range of interest.
- Enter these into the appropriate function. On a TI-84, that's
normalcdffor area between two values ornormalpdffor the density at a point. In Excel, use=NORM.DIST(x, mean, sd, TRUE)for the cumulative probability. - Read the output as the probability associated with your value or range.
- Cross-check against a manual z-table calculation when possible, especially while you're still learning.
The inverse normal function works in the other direction: you input a probability, and it returns the corresponding -value. This is useful for questions like "What score do you need to be in the top 10%?" On a TI-84, use invNorm; in Excel, use =NORM.INV(probability, mean, sd).
Advanced Concepts in Normal Distributions
- The central limit theorem (CLT) states that the distribution of sample means approaches a normal distribution as the sample size increases, even if the original population isn't normal. This is why the normal distribution shows up so often in statistics.
- Skewness describes asymmetry in a distribution. A perfectly normal distribution has zero skew. Positive skew means a longer right tail; negative skew means a longer left tail. When data is noticeably skewed, the normal model may not fit well.
- Kurtosis describes how heavy the tails are compared to a normal distribution. High kurtosis means more extreme outliers; low kurtosis means lighter tails.
- Standardizing values with z-scores lets you compare data from different normal distributions directly. A z-score of 1.2 on one exam means the same relative position as a z-score of 1.2 on a completely different exam, regardless of the original scales.
See Fiveable more often in Google
Mark Fiveable as a preferred source and Google is more likely to show you our guides in Top Stories, with a "preferred" badge in AI Mode and AI Overviews.